The Next Best Action Playbook > Chapter 4: Uplift modeling: find the customers your offer actually moves
Uplift modeling: find the customers your offer actually moves
Uplift modeling is the only model that tells you who to leave alone. Every other model in a growth team’s stack predicts what a customer will do. An uplift model predicts how much a specific action changes what they do, by estimating each customer’s behavior with the action and without it and scoring the difference. That difference is the thing every promotional dollar is actually buying, and most B2C brands have never measured it at the customer level.
The payoff is unusual among models because it comes from spending less. A churn model finds people to contact. An uplift model finds the people among them whose minds your contact would change, and quietly removes everyone else from the list: the customers who were staying anyway, the ones who are gone regardless, and the ones your message would push out the door.
The four groups
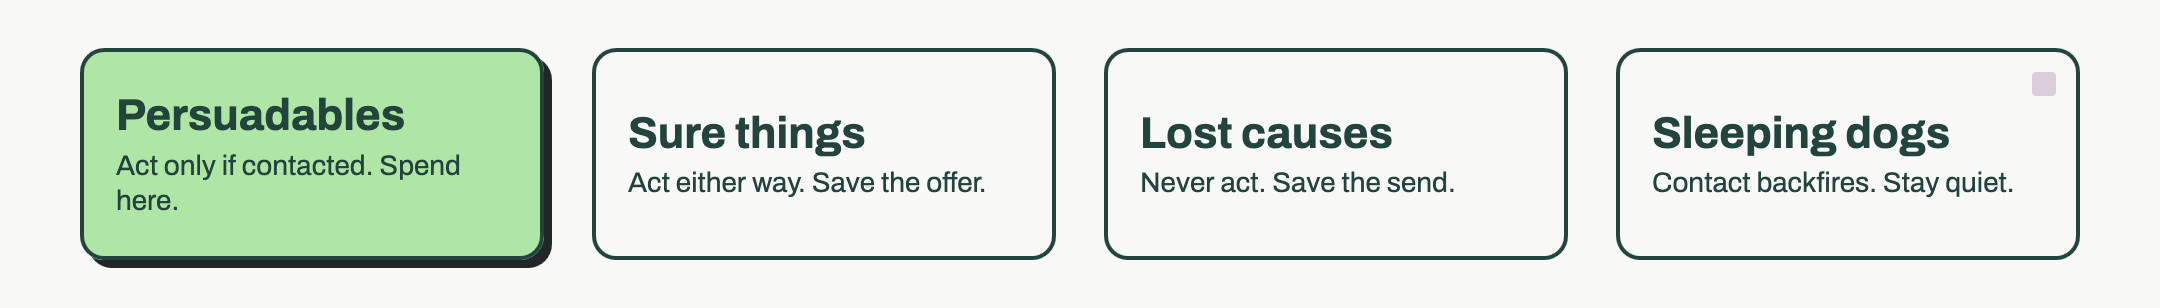
Every customer eligible for an action belongs to one of four groups, defined by what they do with the action and what they’d have done without it.
| Acts if you contact them | Acts if you don’t | What to do | B2C example | |
|---|---|---|---|---|
| Persuadables | Yes | No | Contact them. This is the whole budget. | The subscriber on the fence; the shopper with a full cart and a cooling interest |
| Sure things | Yes | Yes | Leave them alone. They’re already yours. | The coffee subscriber who reorders every 30 days like clockwork |
| Lost causes | No | No | Leave them alone. Nothing lands. | The player who deleted the app; the account holder who already moved every direct deposit |
| Sleeping dogs | No | Yes | Leave them alone, carefully. Contact makes it worse. | The gym member who forgot they’re paying; the streaming subscriber whose renewal email reminds them to cancel |
A propensity model can’t see these groups, because it only predicts the “acts” column. Sure things and persuadables both score high on propensity to renew, and the propensity campaign sends them the same offer. That’s the propensity trap the playbook hub introduced, and it’s expensive enough to deserve its own arithmetic.
Why propensity targeting wastes budget: a worked renewal
Take a subscription with a $120 annual plan and 100,000 subscribers scored as highly likely to renew. The retention team offers all of them 20% off the renewal, a $24 discount. A holdout of similar subscribers gets no offer.
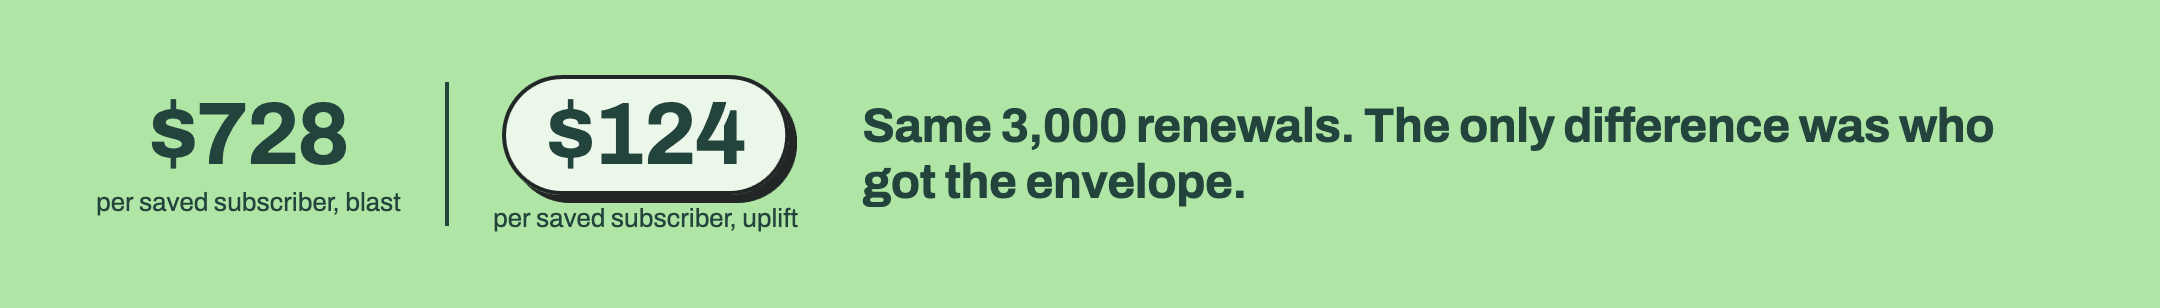
The results come back: 91% of the offered group renews, 88% of the holdout renews. Three points of lift, which is 3,000 renewals the offer caused. The team paid the $24 discount to every renewer, 91,000 of them, for $2,184,000 in forgone revenue. That’s $728 per incremental renewal, on a plan that bills $120 a year.
Now the same campaign with an uplift model. The model scores every one of the 100,000 subscribers on predicted lift, and the top 25,000 (the persuadables) get the offer. Among them, 62% renew with the offer against 50% without: twelve points of lift, which is again 3,000 renewals the offer caused. The discount was paid on 15,500 renewals, $372,000. That’s $124 per incremental renewal.
| Propensity blast | Uplift targeting | |
|---|---|---|
| Offers sent | 100,000 | 25,000 |
| Lift | 3 points | 12 points |
| Incremental renewals | 3,000 | 3,000 |
| Discounts paid | $2,184,000 | $372,000 |
| Cost per incremental renewal | $728 | $124 |
Same number of subscribers saved, a quarter of the offers, about a sixth of the discount spend. And if a kept subscriber is worth, say, $250 over the next few years, the blast lost about $1.4 million and the uplift campaign made about $380,000. One campaign, two outcomes, and the only variable was who got the envelope.
What an uplift model needs: a campaign with a holdout
Uplift models learn from one thing: a past action where some eligible customers randomly got it and some randomly didn’t. The control group is the training data. Without it there’s no “without the action” column to learn from, and no amount of clever modeling can invent one.
Most B2C brands already have this and don’t know it. Any campaign that ran with a holdout, even a small one, even once, is a training set. If you’ve never held anyone out, the fix costs one cycle: run your next retention offer, cross-sell send or win-back campaign with a random 10% of eligible customers excluded, and by the end of the cycle you’ll have what the model needs. Our chapter on measuring retention lift with incrementality covers how to set that holdout up so it stays clean.
Two warnings. The holdout has to be random; “customers we didn’t get to” is a biased control, and a model trained on it learns your old targeting rules instead of the action’s effect. And the test needs to be large enough that the lift is visible above noise, which for a three-point effect usually means tens of thousands of customers per arm. Small brands can still do this; they just need more cycles.
If you have several campaigns with holdouts to choose from, start with the one carrying the biggest budget. The discount that goes to the most customers is the one where sure things cost you the most, so it’s where the first uplift model pays back fastest, and it’s usually the retention offer.
How uplift models are built, in plain words
There are two common ways to build one, and a business user only needs to know what each one produces.
The two-model approach trains one model on the customers who got the action and another on the customers who didn’t, then subtracts the second prediction from the first for every customer. The single-model approach trains one model with “got the action” as an input, then scores each customer twice, once with that input switched on and once with it off, and takes the difference. More recent methods learn the difference directly. All of them produce the same output: a predicted lift, per customer, per action.
That last phrase matters for a next best action program. A menu with five actions on it needs five lift estimates per customer, one for each eligible action, so the arbitration layer can compare a pause offer against a content recommendation against silence for the same subscriber. Our worked discount-campaign example of uplift modeling walks through the single-action version in detail; the decisioning version is the same model run once per action.
Reading an uplift model: where to stop spending
An uplift model’s output is a ranking, and the useful way to read it is to sort customers by predicted lift, split them into ten equal groups, and look at the lift each group actually delivered in the test.
| Decile by predicted uplift | Actual lift in test | Incremental renewals (10,000 per decile) | Cumulative incremental renewals |
|---|---|---|---|
| 1 | +17 points | 1,700 | 1,700 |
| 2 | +10 | 1,000 | 2,700 |
| 3 | +5 | 500 | 3,200 |
| 4 | +3 | 300 | 3,500 |
| 5 | +1 | 100 | 3,600 |
| 6 | 0 | 0 | 3,600 |
| 7 | 0 | 0 | 3,600 |
| 8 | -1 | -100 | 3,500 |
| 9 | -2 | -200 | 3,300 |
| 10 | -3 | -300 | 3,000 |
Read down the last column and the decision writes itself. Offers to the top three deciles produce 3,200 incremental renewals from 30,000 sends. Offers to everyone produce 3,000 from 100,000, because the last three deciles are sleeping dogs, and contacting them cost the program 600 renewals it had already won. The curve rises, flattens, then falls. Stop where it flattens. Past that point, every additional offer is paying to lose a customer.
The same table tells you whether the model is any good. A working uplift model has a steep first decile and a visible negative tail. A model whose deciles all show roughly the same lift has learned nothing about who responds; it’s a propensity model in a costume.
Uplift by industry: the actions it changes most
Retention offers in subscription are where uplift pays first, because the sure things are so numerous. Most high-propensity renewers renew. An uplift model moves the discount from the 88% who didn’t need it to the slice on the fence, and it finds the sleeping dogs whose renewal email was the only reason they remembered to cancel.
Cross-sell in ecommerce is the second place to look. A cross-sell email to everyone who bought the first product reaches a lot of people who’d have found the second product on their own. Uplift scores the email’s effect on category purchase per shopper, and the expansion chapter of the lifecycle playbook shows what the lifecycle team does with that score.
Win-back is where uplift thinking has the longest track record with our customers. Hydrant, a DTC drink-mix brand, built a win-back model on customers who had not made a purchase for at least two months and used it to decide who got the offer. The group the model picked had a 2.6x higher conversion rate and a 3.1x higher average revenue per customer than a control group. The control group is doing two jobs in that sentence: proving the lift, and training the next model.
In gaming, uplift protects revenue as much as retention. Free currency lifts day-7 retention and, for players close to a first purchase, replaces the purchase. An uplift model per action separates the players a gift keeps from the players a gift costs you.
In banking and insurance, uplift mostly finds sleeping dogs: the dormant account holder a “we miss you” message reminds to close the account, and the policyholder a proactive renewal call sends to a comparison site. For them, the best action is on the menu and it’s nothing.
Uplift and incrementality are the same idea at two scales
Incrementality testing asks whether a campaign changed anything, for the whole audience, using a holdout. Uplift modeling asks the same question for each customer, using the same holdout. The test gives you one number; the model gives you a number per person and lets you act on it next time. If your team already runs incrementality tests, you’re one model away from uplift, and the measuring decisioning impact chapter shows how the two feed each other every cycle.
Where we come in
Building an uplift model from your campaign history is the kind of work that used to need a data science team and a quarter. You bring your historical customer data, including the campaign log of who got what and who was held out, and the action you want to aim, the Predictive AI Agent reads that data as it is, trains and validates the propensity and uplift models, and we own the outcome, with a predicted lift per customer per action live in the CRM, ESP or decisioning tool your team already uses. Then the next action gets its own model on the same foundation.
Predict the right move for every customer:
Book a demoFAQ
Can you build an uplift model without a control group?
No. An uplift model learns the difference between customers who received an action and similar customers who didn’t, so it needs a past campaign with a randomly held-out group. If you’ve never run one, run your next campaign with a random 10% of eligible customers excluded; one cycle produces the training data.
How big does the test behind an uplift model need to be?
Large enough that the lift is visible above noise. For an effect of a few percentage points, that usually means tens of thousands of customers in each of the treated and control groups. Smaller brands can get there by pooling several cycles of the same campaign, as long as each one had a random holdout.
What is a sleeping dog in uplift modeling?
A sleeping dog is a customer who would have acted (renewed, stayed, bought) if left alone, but acts less when contacted. Common examples are subscribers who forgot they were paying until a renewal email reminded them, and dormant account holders a “we miss you” message prompts to close the account. Uplift models identify them so they receive no contact.