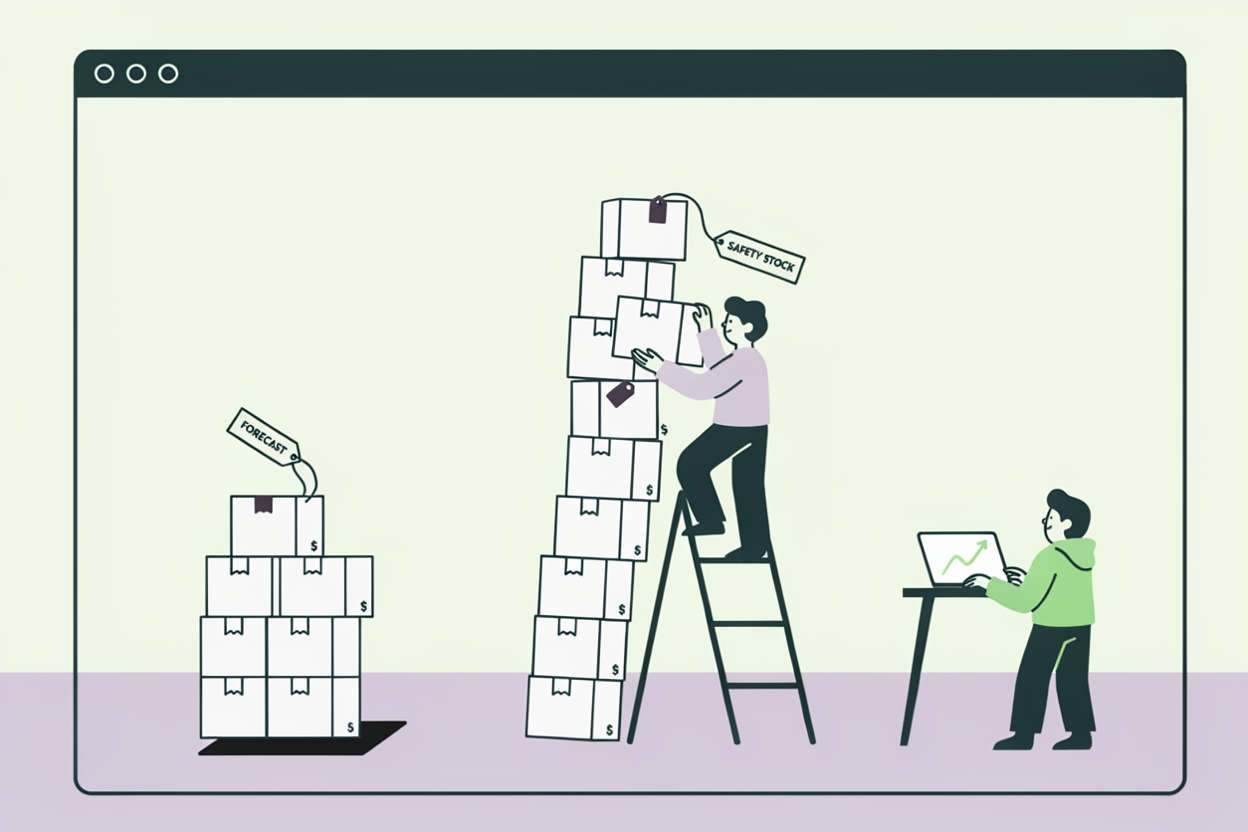
Every safety stock formula is a bill for forecast error, and none of the pages that teach the formula mention who sent it. They walk you through the Z-score, the standard deviation, the square root of lead time, and then stop, as if the inputs were weather. The biggest term in that formula is the size of your forecast miss, and it’s the one term you can shrink without accepting more stockouts.
Safety stock is the extra inventory you hold above expected demand to protect against variability in demand and supplier lead time. There are two standard ways to calculate it: a basic formula that compares worst-case usage against average usage, and a statistical formula that sets the buffer from a target service level, a Z-score, and the standard deviation of demand. Both are below, worked through on one product, with a calculator, the reorder point formula that uses the result, and an honest section at the end on what happens to the buffer when the forecast feeding it gets better.
If you run planning for a company where the buffer is a large share of working capital, that last part is the reason to read this instead of a vendor’s formula page. It’s the same reason AI supply chain optimization tends to start with the forecast rather than the warehouse.
What is safety stock?
Safety stock (sometimes called buffer stock) is the quantity of a product you keep on hand beyond what you expect to sell during the time it takes to replenish. Its only job is to absorb surprises: a week where demand runs hot, a shipment that lands four days late, or both at once.
Hold too little and you stock out, lose the sale, and often lose the customer to whoever had it in stock. Hold too much and you tie up cash, pay to store and insure product that isn’t moving, and eventually mark it down. Safety stock calculation is the exercise of choosing a number between those two failures on purpose, per SKU, rather than by feel.
Two things drive the number. How variable your demand is, and how variable your lead time is. Everything else in the formulas is a way of expressing how much of that variability you want to be protected against.
It helps to keep safety stock separate from cycle stock in your head. Cycle stock is the inventory you expect to sell between one delivery and the next, and it rises and falls with every order. Safety stock sits underneath it and, on a normal cycle, never moves. When you see a warehouse that’s “full” of a product that sells steadily, the question to ask is which of the two it’s full of. Excess cycle stock is an ordering problem. Excess safety stock is a variability problem, and usually a forecasting one.
The basic safety stock formula (max-average method)
The simplest formula compares the worst case you’ve seen against the average:
Safety stock = (Maximum daily demand × Maximum lead time) − (Average daily demand × Average lead time)
It asks: if the busiest day I’ve ever had coincided with the slowest delivery I’ve ever had, how many extra units would I need? Then it holds that many.
Take a product that sells 100 units a day on average and 150 on its best day, and your supplier takes 10 days on average and 14 on the worst delivery you’ve logged:
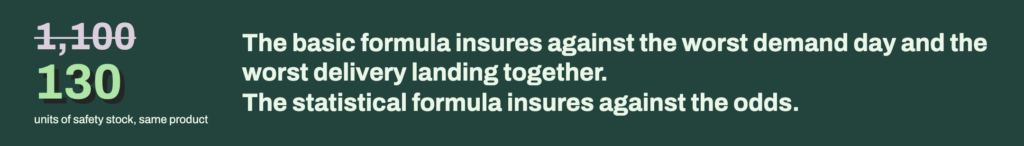
(150 × 14) − (100 × 10) = 2,100 − 1,000 = 1,100 units of safety stock
It’s popular because it needs four numbers you already have and no statistics. It has two honest drawbacks. First, it assumes the worst demand and the worst lead time hit together, which almost never happens, so it overprotects and ties up cash. Second, “maximum” is a fragile input. One freak day or one port strike in your history sets the buffer for every product forever. On the example above, the basic method holds 1,100 units to cover a coincidence that may occur once in several years.
The statistical safety stock formula (Z-score and service level)
Statistical safety stock replaces “worst case ever” with “how sure do I want to be”:
Safety stock = Z × σdemand × √(Lead time)
Each variable in one sentence:
- Z is the Z-score for your target service level, taken from the standard normal distribution. It converts “I want to be in stock 95% of cycles” into a multiplier.
- σdemand (sigma) is the standard deviation of daily demand, a measure of how far actual days stray from the average.
- √(Lead time) scales the daily variability up to the length of the replenishment window. Variability compounds with time, but as a square root rather than in a straight line.
Service level is the probability of not stocking out during one replenishment cycle. Pick it by the cost of a miss, and read the Z-score off this table:
| Service level | Z-score |
| 90% | 1.28 |
| 95% | 1.65 |
| 98% | 2.05 |
| 99% | 2.33 |
Notice the shape of that table. Going from 90% to 95% costs about 0.4 of a Z. Going from 98% to 99% costs nearly 0.3 for one extra point of protection. Each additional point of service level is more expensive than the last, which is why “99% on everything” is a policy that quietly eats a warehouse.
Using the same product (average demand 100/day, 10-day lead time) and a standard deviation of daily demand of 25 units, at a 95% service level:
1.65 × 25 × √10 = 1.65 × 25 × 3.16 = 130 units
One product, one supplier, and the statistical formula holds 130 units where the basic formula held 1,100. The difference is the price of assuming every bad thing happens on the same day.
One extension you’ll see on the more careful formula pages accounts for lead-time variability as well as demand variability:
Safety stock = Z × √( (Lead time × σdemand²) + (Average demand² × σlead time²) )
On our product, if lead time varies with a standard deviation of 2 days, that version gives 1.65 × √(10 × 625 + 10,000 × 4) = 1.65 × 215 = 354 units at 95%. The jump from 130 to 354 is entirely the supplier’s unreliability. Worth knowing, because it tells you where the buffer is coming from: in this case, most of it is lead time, and no forecast improvement touches that. A supplier conversation does.
Worked example: calculating safety stock step by step
Pulling the numbers together for one product, start to finish.
Step 1. Gather the inputs. From your sales history and supplier records:
| Input | Value |
| Average daily demand | 100 units |
| Standard deviation of daily demand | 25 units |
| Maximum daily demand observed | 150 units |
| Average lead time | 10 days |
| Standard deviation of lead time | 2 days |
| Maximum lead time observed | 14 days |
| Target service level | 95% |
Step 2. Basic method. (150 × 14) − (100 × 10) = 1,100 units.
Step 3. Statistical method, demand variability only. Z for 95% is 1.65. 1.65 × 25 × √10 = 130 units.
Step 4. Statistical method, demand and lead-time variability. 1.65 × √(10 × 25² + 100² × 2²) = 1.65 × √46,250 = 354 units.
Step 5. Sanity check against cost. At a landed cost of $30 a unit, the three answers tie up $33,000, $3,900, and $10,600 respectively in inventory that exists only to absorb surprises. That spread is the whole point of doing the calculation instead of using a rule of thumb.
Step 6. Choose. If this supplier really does swing by two days on a ten-day lead time, 354 is the honest number at 95%, and the next question is whether a 2-day swing is something you can fix. If lead time is stable, 130 covers you. Either way, 1,100 is buying insurance against a day that almost never comes.
Safety stock calculator
Both safety stock formulas, a service level dropdown, and the reorder point. Change any input and the results update. Everything runs in your browser and nothing is saved.
Your numbers
Pull these from sales history and supplier records. Daily units and days.
Statistical safety stock at 95% service level
130units
Z (1.645) × σ demand × √ lead time
Pecan builds the demand forecast that shrinks the σ. See it on your SKUs.
Prefer a spreadsheet? It has both formulas, the combined-variability version, a service-level dropdown with the Z-score lookup built in, and the reorder point. Paste your own numbers over the yellow cells.
Building it yourself in Excel is also easy, because the statistical formula is one line. With your daily demand history in column B and a 10-day lead time:
=NORM.S.INV(0.95) * STDEV.S(B2:B366) * SQRT(10)
NORM.S.INV turns the service level into the Z-score, STDEV.S gives you sigma, and the square root handles lead time.
The reorder point formula (and how it uses safety stock)
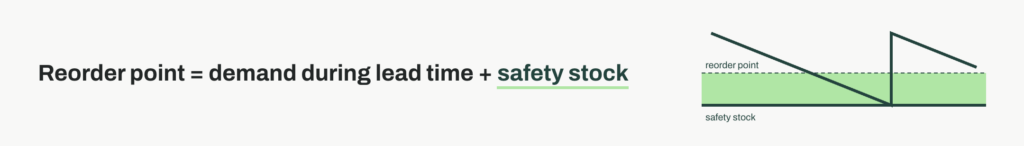
Where safety stock tells you how much cushion to hold, the reorder point tells you when to place the next order so that cushion is rarely touched.
Reorder point = (Average daily demand × Average lead time) + Safety stock
That first term is the demand you expect to see while you wait for the order to arrive. The second is the buffer for when expectation is wrong. When on-hand inventory drops to the reorder point, you order.
On our product, using the 130-unit statistical buffer:
(100 × 10) + 130 = 1,130 units
So when stock hits 1,130, you reorder. Over the next 10 days you expect to sell about 1,000, leaving the 130 buffer intact on a normal cycle and available on a bad one. If you used the combined-variability buffer instead, the reorder point would be 1,354.
A couple of practical notes. The reorder point moves whenever average demand or lead time moves, so it needs to be recalculated as often as your forecast is, which is where a demand planning cadence matters more than the arithmetic. And if you order in fixed lot sizes or on a fixed schedule rather than at a trigger point, the same safety stock still applies. Only the ordering rule changes.
What is a good safety stock level?
There’s no single good number, and any page that gives you one is guessing about your margins. The right buffer depends on what a stockout costs you relative to what holding stock costs you, and that ratio differs by product.
Roughly, by product type:
- High-margin, high-loyalty products where a stockout sends a customer to a competitor for good: service levels of 97 to 99% are usually justified. The buffer is expensive and the miss is more expensive.
- Commodity or low-margin products with easy substitutes: 90 to 95% is common. Beyond that, each point of protection costs more than the sales it saves.
- Slow movers and long-tail SKUs: often the honest answer is a lower service level or make-to-order, because the carrying cost of protecting a product that sells twice a month is out of proportion to the revenue.
Expressed as a percentage of cycle stock, buffers commonly land anywhere between 10% and 50%. On our example product, the 130-unit statistical buffer is 13% of the 1,000 units of lead-time demand. The basic formula’s 1,100 is 110%. Both are “a safety stock percentage.” Only one of them is reasonable.
Better than “what percentage” is the question is “what service level per SKU, and what does each point cost.” That’s the framing that survives contact with a CFO.
The part the formulas hide: safety stock is the price of forecast error
Look at the statistical formula one more time. Z is a policy choice. Lead time is your supplier’s. That leaves σ, the standard deviation of demand, as the term that decides how big the buffer is, and here is what most formula pages skip: σ is really the standard deviation of your forecast error, not of demand itself.
When your “forecast” is last year’s average, every day’s deviation from that average is a miss, and σ is large. If your forecast tracks seasonality, promotions, and the weather, most of those deviations were predicted, and the unexpected part left over is much smaller. The buffer only has to cover the part you didn’t see coming.
Run it on our product. Our naive forecast had a σ of 25 and needed 130 units at 95%. Suppose a better forecast brings the standard deviation of the error down to 15. The buffer becomes 1.65 × 15 × √10 = 78 units. Same service level, same supplier, 40% less inventory sitting on the shelf, because 40% less of demand was a surprise. Multiply that across a catalog and it’s the difference between a warehouse expansion and not needing one.
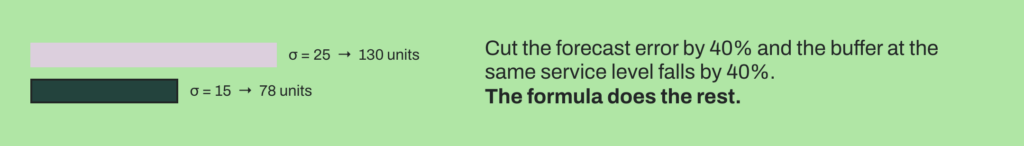
This is why we’d argue that predictive inventory management starts with the forecast and only then moves on to reorder rules. The rules are downstream. Improve demand forecasting accuracy and every safety stock formula in the building recalculates smaller on its own.
Customer evidence points the same way. A fast fashion retailer that replaced traditional forecasting with Pecan’s demand forecasts cut overstock by up to 50% and lifted sales 10 to 25% from fewer stockouts, which is what “smaller buffer, same service level” looks like on a P&L. A Tier II high-tech manufacturer that had been forecasting subcomponent demand by hand built a demand forecast model in under 14 days and reported 25% inventory cost savings alongside a 15% labor saving and 75 to 85% forecast accuracy. Kenvue, working with Pecan’s DemandForecast.ai team, reduced MAPE by 37% in its first year. Across 15 demand forecasting deployments we reviewed, Pecan’s forecast beat the customer’s incumbent forecast in every benchmarked case, cutting forecast error by 15% to 56% with an average improvement of roughly 30%. Run that through the formula and a 30% smaller error is a buffer roughly 30% smaller at the same service level.
None of that required a data science team. Pecan’s Predictive AI Agent takes a question like “what will demand be for each SKU next month” and handles the data preparation, the feature engineering, the model building and validation, and the delivery of the forecast into the planning tool you already use. It works on the sales and supplier history you have today, gaps and all. The service level stays your call. Sigma gets smaller.
One note on what “forecast error” means here, since planning teams usually track it as MAPE or bias rather than a standard deviation. The two are cousins. MAPE is the average size of the miss as a share of actual demand, and the standard deviation of error is how widely those misses scatter. A forecast that cuts MAPE by a third will, in most product histories, cut the standard deviation of error by something similar, and that’s the figure the formula takes. If your planning software only reports MAPE, that’s still enough to know which direction the buffer is heading.
To see what your buffer looks like with a better forecast underneath it, book a demo and bring a few SKUs with their current safety stock. We’ll model the demand and you can rerun the formula.
What is a good safety stock percentage?
How do I calculate safety stock in Excel?
What is the difference between safety stock and reorder point?
Can you reduce safety stock without more stockouts?
Omer is a Data Scientist at Pecan AI with an M.Sc. in Industrial Engineering, bringing a strong analytical foundation built across multiple industries. He combines structured problem-solving with cross-disciplinary collaboration to drive meaningful impact through data.