The Next Best Action Playbook > Chapter 5: Measuring decisioning impact
Measuring decisioning impact
A decisioning program is judged on the decisions it didn’t make, too. A campaign gets measured by what it sent. A next best action program chooses, for every customer, between several actions and silence, so its results have to account for the offers it withheld, the contacts it skipped and the customers it left alone on purpose. Three numbers keep it honest: a global holdout that measures the whole program against the old way, a per-action lift that measures each move against the customers who were eligible for it and didn’t get it, and a contact budget that prices the fatigue every send spends.
Teams that measure only the first number can’t tune anything. Teams that measure only the second can’t prove the program is worth its budget. You need all three, and the good news is that they share the same plumbing.
The global holdout
The global holdout is a random slice of your customer base, usually 5% to 10%, that the decisioning engine never touches. It exists for the life of the program, it’s re-randomized once a year so nobody sits in it forever, and it answers the only question finance really asks: compared to what?
There are two ways to design it, and large brands should run both. A no-contact holdout receives nothing from any decisioned journey, which measures the total value of acting at all. A legacy-rules holdout keeps receiving the old program (the segment campaigns, the calendar sends, the blanket offers), which measures what decisioning added over the way things used to work. The second one is the number that gets a program renewed, because it isolates the decision quality from the mere fact of contacting people.
Per-campaign holdouts can’t replace it. They measure one action at a time, and a decisioning program’s value includes interactions between actions (the subscriber who got the content recommendation instead of the discount) and the contacts it suppressed. Only a slice that sits outside the whole engine captures that. Our chapter on measuring retention lift with incrementality covers the mechanics of keeping a holdout clean; the global version follows the same rules at program level.
How big should it be? Big enough to see the effect you’re claiming. A program expecting to move revenue per customer by one or two percent on a base of two million customers can prove it with 5%. A base of 200,000 needs 10%, and a base of 50,000 should expect to wait two or three cycles before the number settles. Teams that shrink the holdout to “save” revenue usually end up with a program they can’t defend, which costs more than the 5% ever did.
The objection you’ll hear is that holding customers out leaves money on the table. It does, in the exact amount the program is worth per customer, times 5%. That figure is also the first line of the business case, so the holdout pays for itself the first time someone asks for the budget.
Per-action lift
Each action in the menu gets its own measurement: customers who were eligible for it and received it, against customers who were eligible for it and were randomly held back. The held-back share can be small, 10% of the eligible pool is typical, because you only need enough of them to see the lift above noise.
The table that comes out of this is the one the lifecycle team lives in.
| Action | Eligible | Treated | Control | Outcome, treated | Outcome, control | Lift | Cost of action | Net |
|---|---|---|---|---|---|---|---|---|
| Retention pause offer | 60,000 | 54,000 | 6,000 | 63% retained at 90 days | 54% | +9 points, 4,860 subscribers | $243,000 | $631,800 |
| Cross-sell content email | 400,000 | 360,000 | 40,000 | 7.1% bought in category in 30 days | 5.9% | +1.2 points, 4,320 orders | ~$0 | $237,600 |
| Win-back offer, 15% off | 120,000 | 108,000 | 12,000 | 11% returned in 60 days | 6% | +5 points, 5,400 returns | $142,560 | $235,440 |
(Illustrative numbers. Net values a kept subscriber at $180 of twelve-month revenue, a cross-sell order at $55 margin and a win-back order at $70 margin before the discount; the pause offer’s cost is one free month taken up by 30% of treated subscribers; the win-back discount is paid on every returning order in the treated group.)
Three things to read off that table. The cheapest action has the smallest lift and the best ratio, which is normal and is why content keeps beating coupons. The retention offer is the most valuable per customer and the most expensive per send, so its threshold deserves the most attention. And every row has a control column, which means every action can be defended on its own, and every action can be cut if its net goes negative. That last point is what per-action measurement is for.
Incremental revenue per contact, and the contact budget
A decisioning program has a currency most campaign teams never price: the customer’s attention. Every send spends a little of it. Past some number of contacts a month, opens fall, unsubscribes rise, and the next action’s lift shrinks whatever the model predicted. That’s the fatigue cost, and it’s measured the same way as everything else: the global holdout’s unsubscribe and opt-out rates against the program’s.
The useful metric is incremental revenue per contact: the lift an action produces divided by the number of contacts it took. It turns the arbitration into a budgeting question. If a customer can receive four contacts a month before fatigue bites, the engine spends those four on the actions with the highest incremental revenue per contact, and “nothing” wins whenever the best available action’s expected lift is lower than the fatigue it would cost.
Do nothing is an action, and it’s measured like one. SciPlay’s retargeting program is the cleanest example we have: by predicting which lapsed players would come back on their own and leaving them alone, SciPlay saves millions per year through increased retargeting efficiency. The money came from the contacts the program chose not to make.
Tuning the arbitration
Per-action lift is also how the engine learns. The arbitration layer picks one action per customer by expected value, which means the second-best action never gets sent to that customer, and you never find out whether it would have done better. The fix is an explore slice: a small share of decisions, 5% is common, where the engine picks randomly among the eligible actions instead of by score. It costs a little lift today and buys the evidence to re-weight the arbitration next cycle.
Reading the explore slice is the quarterly ritual. When the second-ranked action beats the chosen one for a definable group (price-driven churn risk in the ad-supported tier, say), the arbitration weights move. When an action’s lift decays across cycles, the model behind it is drifting and needs retraining on fresher history. When the whole table shifts in the same direction in November, that’s seasonality, and the window for the next cycle should be set with it in mind rather than against last quarter’s baseline.
One person can run all of this: whoever owns the measurement, reads the table once a cycle, and has the authority to change a weight.
The dashboard that matters
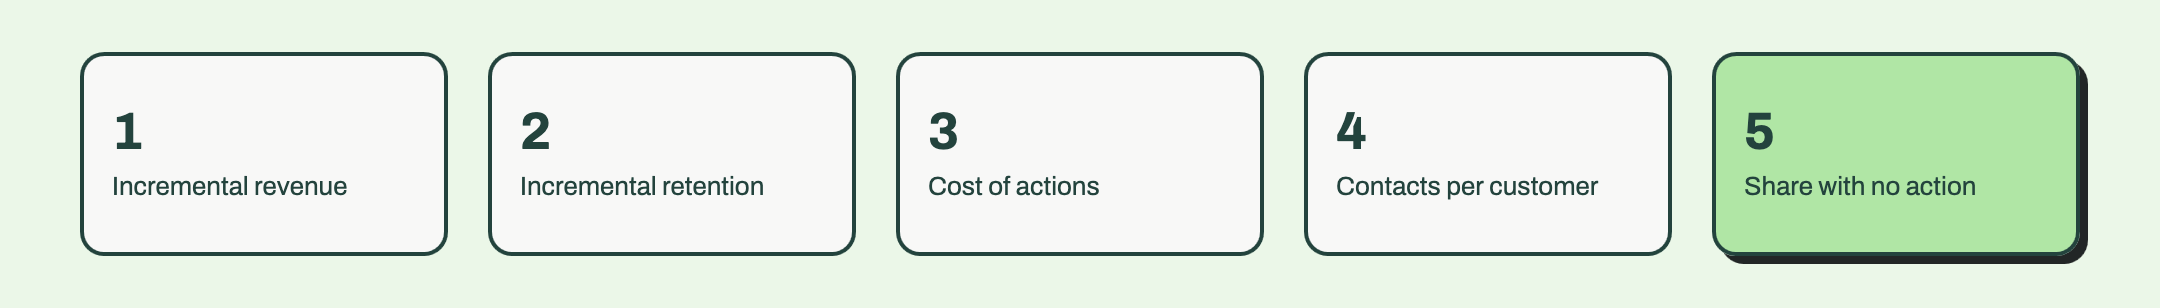
Five numbers, reported every cycle, against the global holdout wherever one applies.
Incremental revenue: program population against the legacy-rules holdout, per customer and in total. Incremental retention: the same comparison on the retention outcome, because revenue lags it. Cost of actions: discounts, free months, call minutes and media, summed per action and in total. Contacts per customer per month: the fatigue budget, with unsubscribe lift beside it. And the share of customers who received no action this cycle, which should be large, and which a program that only reports sends will never show you.
Anything else is a diagnostic. These five are the program.
A worked quarter
Put the three actions from the table above into one quarter for a subscription brand with two million customers, 5% of them in a legacy-rules holdout, and the report reads like this.
| Measure | Result |
|---|---|
| Incremental revenue (sum of per-action lift) | $1,490,400 |
| Cost of actions | $385,560 |
| Net from the three actions | $1,104,840 |
| Revenue per customer, program vs legacy-rules holdout | $61.40 vs $60.60, +1.3% |
| Program-wide incremental revenue implied by the global holdout | about $1.5 million across 1.9 million customers |
| Contacts per customer per month | 1.4 under decisioning vs 2.6 under the old rules |
| Unsubscribe rate in the quarter | 0.9% vs 1.6% |
| Share of customers receiving no action | 58% vs 12% |
The two routes to incremental revenue (the per-action sum and the global holdout) land within noise of each other. That agreement is the point. When the per-action table says $1.5 million and the global holdout says $4 million, something is being double counted or the holdout is contaminated; when they disagree the other way, actions are interfering with each other. Two measurements that agree are how you know the number is real, and the number here was earned with 46% fewer contacts.
The last row is the one to put in front of the CFO. More than half the base got nothing this quarter, revenue per customer went up anyway, and the fatigue the old program was spending every month was returned to the customer.
Where we come in
The measurement is yours; the predictions behind it are the part we deliver. You bring your historical customer data, including the campaign log of who got what and who was held out, and the decisions you want to make, the Predictive AI Agent reads that data as it is, trains and validates the propensity and uplift models, and we own the outcome, with scores and drivers live in the CRM, ESP or decisioning tool your team already uses, where the holdouts and the per-action lift are read. As the explore slice and the holdouts produce new evidence each cycle, the models stay accurate as your customers change.
Predict the right move for every customer:
Book a demoThat closes the ladder. Back to the Next Best Action Playbook for the full picture, or, if the first decision you’ll make is who gets the retention offer (it usually is), start with the B2C Churn and Retention Playbook, which measures the leak that decisioning will close.