A churn model goes live in January. It scores well, the retention team trusts the list it produces, and for a few months the customers it flags keep turning out to be the ones who leave. By July it’s missing half of them. Nobody touched the model.
That’s model drift. Most engineering blogs treat it as a statistics problem. We think it’s a calendar problem first, because drift almost always has a date on it. Somewhere in your company, pricing changed, a promo ran, a new channel opened or a tracking event broke, and the model found out last. Statistical tests confirm drift after it has happened. Your business calendar can see it coming.
Everything below is written for the person who owns the prediction, so each concept comes with a business example.
What is model drift?
Model drift is the decline in a predictive model’s accuracy over time, caused by changes in the real-world data it scores or in the relationship between that data and the outcome it predicts. The model stays exactly as it was trained. The world it was trained on moves. Some teams call the same thing model decay.
It matters because nobody switches a model off when it starts slipping. The churn list still lands in the CRM every Monday. The demand forecast still feeds the purchase orders. Decisions keep running on stale predictions, and the gap stays invisible until the outcomes come in. Accuracy at launch is a snapshot. Model reliability is what that accuracy does over the following year, and drift is the main thing that erodes it.
Types of model drift
Most pages split drift into two buckets. We find four more useful, because each enters the pipeline at a different point and asks for a different fix.
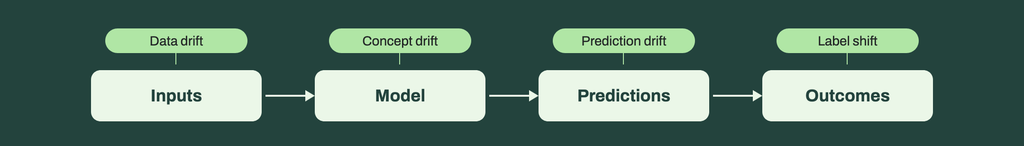
Data drift (covariate shift). The inputs change. A lead scoring model was trained when most leads came from webinars. Now half arrive through a partner integration with different form fields and engagement patterns, and the model is scoring a population it never learned.
Concept drift. The relationship between inputs and outcome changes. Heavy product usage used to mean a loyal customer. After a pricing change, the heaviest users on the old plan are the angriest ones, and the same input now points the other way. The next section goes deeper on this one, because it hurts most.
Prediction drift. The model’s outputs shift. Last quarter it flagged 8% of customers as high risk. This quarter it flags 20%. You can see this the day it happens, long before you know who churned, which makes it a useful early signal even though it can’t tell you why.
Label shift. The base rate of the outcome changes. A demand forecast was trained during a stretch of steady growth, then a competitor opened two miles away and baseline demand dropped. The inputs look the same, and the model’s idea of “normal” no longer holds. This one also goes by target drift, and the short explainer on label stability in our help center walks through the patterns it takes: gradual, sudden, recurring and short blips.
The diagram below shows where each type enters the pipeline: data drift with the inputs, concept drift in the model’s learned logic, prediction drift in the scores, label shift in the outcomes.
What is concept drift?
Concept drift is a change in the link between your inputs and the outcome you’re predicting, so a pattern the model learned stops being true. The data can look perfectly normal. The meaning of the data has moved.
Take discount usage. For years, customers who redeemed discounts were your most engaged buyers, and the churn model learned “uses discounts, stays.” Then marketing moved discounts from loyalty rewards to win-back offers, and the people redeeming them became the ones already halfway out the door. Same column, same values, opposite signal. The model keeps scoring discount users as safe, so the retention team stops calling exactly the people it should.
Researchers who study this (Gama and colleagues’ survey on concept drift adaptation is the standard reference) describe four patterns: sudden, incremental, gradual and recurring. A pricing change is sudden, a slowly maturing user base is incremental, a new sales ICP phasing in over a quarter is gradual, and seasonality is recurring. A model that “drifts” every December may simply need a December in its training data.
Concept drift is the hardest type to catch because input monitoring can’t see it. The only evidence is in the outcomes, and outcomes arrive late (more on that below). A retrain alone rarely fixes it, either. The model usually needs a new feature that captures the new driver, like which kind of offer the discount came from.
Data drift vs model drift
The two terms get used interchangeably, which causes real confusion the day a dashboard turns red. Data drift is a change in the inputs. Model drift is a change in results. One is a possible cause, the other is the effect you care about.
| Data drift | Model drift | |
| What changes | The inputs the model scores: feature distributions move away from the training data | The model’s performance: accuracy, lift or calibration measured against real outcomes |
| How you spot it | Compare live feature distributions with the training data (PSI, KS test) | Compare predictions with outcomes as they arrive |
| What to do | Find the source (a real change in behavior, or a broken pipeline), then retrain if performance follows | Retrain, add features or rebuild, depending on which type of drift caused it |
You can have data drift with no model drift (a new channel brings in customers who look different but churn for the same reasons), and model drift with no visible data drift at all, which is concept drift. That’s why you monitor both layers.
What causes model drift in business predictions
For business models, the causes are rarely mysterious. They’re decisions and events, most of them internal, nearly all of them with a date attached.
- Seasonality. Black Friday, back to school, fiscal year-end. A model trained on eight months of data has never seen the ninth.
- Pricing and promotions. A new tier, a bundle, a promo that changes who buys and why. The most common source of sudden concept drift.
- New channels. A partner integration, a marketplace listing, a campaign on a platform you’ve never used, each bringing in a population with different habits.
- Product launches. A new feature changes what “engaged” looks like, and a new SKU quietly cannibalizes an old one.
- Upstream data changes. A renamed field, a changed event name, a tracking pixel that stopped firing. The sneakiest kind, because it looks like a behavior change (everyone stopped clicking) when the click simply stopped being recorded.
In demand forecasting the usual suspects are promotions and supply surprises, and our guide to demand forecasting accuracy lists the rest. Look down the whole list and one thing stands out: someone in your company knew about each of these events before the model did.
Which suggests a cheap habit. Keep a model change log, a shared doc where anyone who changes a price, launches a promo, renames a field or opens a channel adds one line with the date. Five minutes a week, and the next time a dashboard dips you’ll know whether to look at the model or the pipeline.
How to detect model drift
Model drift detection works in two layers, and you need both because they catch different things at different times.
Watch the outcomes. As real results arrive, compare them with what the model predicted: accuracy and precision for a churn or lead model, lift against a random guess, calibration (did the customers scored at 70% risk churn roughly 70% of the time?), MAPE or WMAPE for a forecast. This is ground truth. It’s also slow.
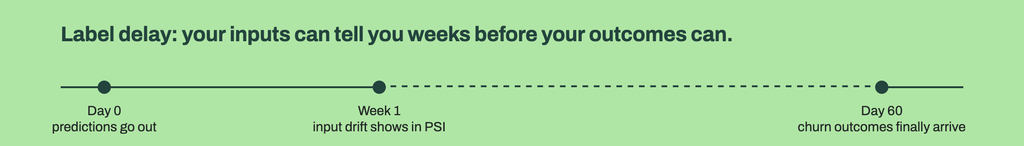
That slowness has a name: label delay. A churn model that predicts cancellation within 60 days can’t be graded for 60 days. A lead score for a quarter-long sales cycle waits a quarter. By the time outcome metrics confirm drift, you’ve been acting on stale predictions for weeks.
Watch the inputs. Compare the distribution of each feature in this week’s scoring data with the distribution the model was trained on. Two tests do most of the work. The Population Stability Index (PSI) scores how far a distribution has moved; a value above 0.2 is the common rule of thumb for a shift worth investigating. The Kolmogorov-Smirnov (KS) test checks whether two samples plausibly come from the same distribution. Add prediction drift (the share of high-risk scores this week versus last) as a third gauge. None of these need outcomes, which makes them your early warning.
Two more things belong on the same dashboard: a feature whose null rate jumps from 2% to 40% (a broken feed, which retraining can’t fix), and a feature that suddenly matters far more or far less to the model than it did at training time, often the first visible sign of concept drift.
Whatever you use for monitoring models in production, aim for input statistics on every scoring run, outcome metrics as labels arrive, and an alert threshold on each.
How to fix model drift: retrain, recalibrate or rebuild
The right fix depends on which type of drift you found, and on whether the pipeline is healthy. A short decision guide:
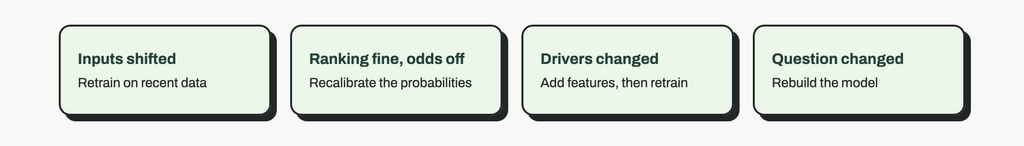
Fix the pipeline first. If a field broke or got renamed, retraining teaches the model that the broken value is normal. Repair the feed and re-score before you touch the model.
Inputs shifted, relationship holds (data drift): retrain on recent data. The model’s logic is fine. It needs to see the new population. A scheduled retrain handles most of this on its own.
Ranking is fine, probabilities are off (prediction drift with stable lift): recalibrate. If the top decile still contains most of the churners but a “70% risk” score now churns 45% of the time, adjust your thresholds or recalibrate the probabilities and skip the full retrain.
The drivers changed (concept drift): add features, then retrain. Capture the new driver explicitly: offer type, plan tier, acquisition channel, promo flag. Retraining without the new feature gives you a model that’s confidently wrong in a fresh way.
The question changed: rebuild. A new product line, a new definition of churn, a new segment, a forecast that now has to be weekly instead of monthly. That’s a new target and a new training window, and the old model would mostly carry its assumptions forward.
One habit makes all of this easier: keep the previous model version. Retrains occasionally come out worse (one stockout month in the training window will do it), and a rollback that takes minutes beats an investigation that takes a week.
How often should you retrain a model?
Two approaches, and for most teams the answer is both.
Scheduled retraining runs on a fixed cadence: weekly, monthly, quarterly. It’s simple and predictable, and it catches gradual and incremental drift without anyone having to notice.
Trigger-based retraining runs when a monitor fires: PSI crosses 0.2 on an important feature, lift drops below a floor, or an event lands in the change log (price change, new channel). It catches sudden drift that a monthly schedule would miss by weeks.
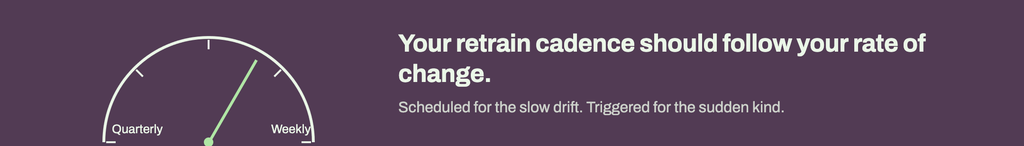
The cadence itself should follow how fast your business changes, which is a different number for every company. A demand model for a seasonal retailer running weekly promos may want weekly retrains plus a trigger. A B2B lead model with a six-month sales cycle might be fine quarterly. If you’re not sure, start monthly, add input monitoring, and let the triggers tell you whether monthly is too slow.
How we handle model drift at Pecan
Before a model goes live, the Predictive AI Agent runs automated health checks on every model it trains and validates: a benchmark comparison against a random guess and a rule-based model, a leakage test, a performance stability check for overfitting, a target drift check and a data volume check. The target drift check looks for a correlation between the label and time inside the training window and, when it finds one, recommends a later start date for training so the model learns from the period that looks like today’s business. Each check comes with a plain-language explanation and a suggested fix.
After deployment, predictions run on your schedule and land in your CRM, warehouse or planning tool, the agent monitors performance and flags when a model needs attention, and retraining happens in the same place, on your historical data as it is.
CAA Club Group runs its roadside assistance forecasts this way: short-term call-volume forecasts twice a week, daily when winter weather hits, and a capacity planning model retrained once a quarter. Their cadence follows their weather, which is the whole idea.
If a churn, LTV or demand model of yours has been quietly slipping, book a demo and we’ll walk you through how the health checks and monitoring work.
What does model drift mean?
What is the difference between data drift and model drift?
How do you fix model drift?
What's the difference between data drift and concept drift?
Is model drift the same as overfitting?